Leaky ReLU
Bases: Activation
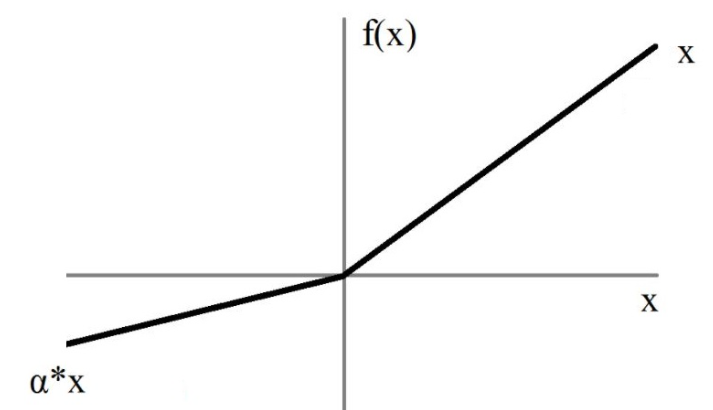
Leaky Relu is a modified version of the standard ReLU activation function designed to prevent "dead" neurons.
Instead of outputting zero for all negative inputs, it allows a small, non-zero linear slope (typically α = 0.01), ensuring a continuous gradient that allows neurons to keep learning during backpropagation.
Parameters:
| Name | Type | Description | Default |
|---|---|---|---|
alpha
|
float
|
determins the slope for negative inputs |
0.1
|
ntk.Leaky_Relu()